Microsoft Open-Sources ThinkingBox to Benchmark AI Agent Side Effects
Microsoft has released ThinkingBox, an open-source evaluation framework that verifies AI agents by inspecting tool side effects rather than transcripts.
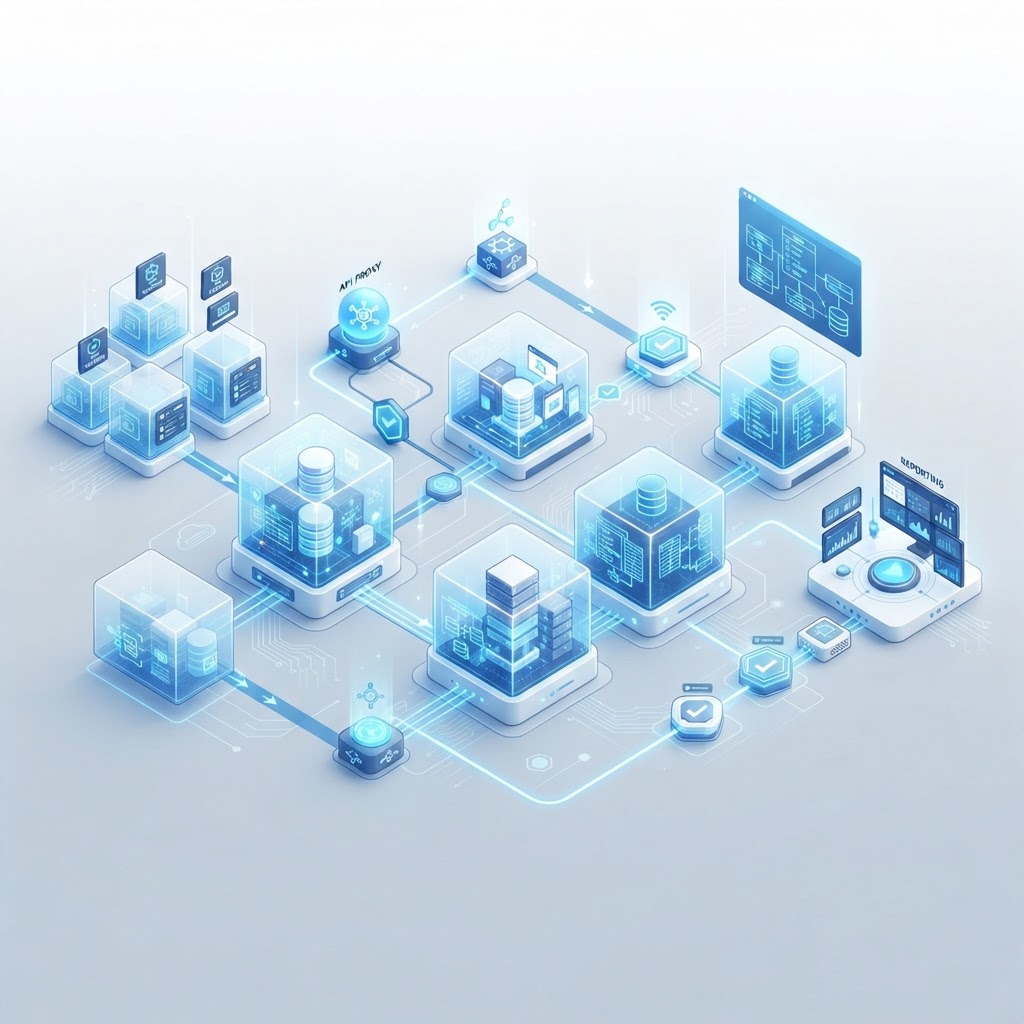
ThinkingBox evaluates LLM agents inside isolated MCP tool environments by checking side effects and database states.
- Microsoft introduced ThinkingBox, a framework designed to verify if LLM agents complete tasks by evaluating stateful tool side effects instead of relying on conversational transcripts.
- The system separates the core CLI and execution loop from the dataset repository, incorporating the Model Context Protocol (MCP) to manage tool environments.
- Accompanying the framework is ThinkingBox-Bench, a benchmark containing 507 executable tasks across five business domains tested against 12 models.
Verifying Agent Execution Beyond Conversational Transcripts
Evaluating large language model (LLM) agents often relies on inspecting conversational transcripts or enforcing rigid execution paths. However, an agent can report that an action succeeded while failing to execute the underlying tool call. In a technical overview on Microsoft Command Line, Principal Machine Learning Engineer Liang-Chun Tsai illustrated this challenge using a hotel reservation request: an agent may inform a user that a quiet-room preference was saved, while the backend database record remains unaltered. Evaluating only conversational outputs produces a false positive.
To address this discrepancy, Microsoft has open-sourced ThinkingBox, an evaluation and execution harness that tests whether autonomous agents complete tasks by directly inspecting the stateful side effects left in tool environments.
The Architecture of ThinkingBox
ThinkingBox relies on a decoupled architecture split into two dedicated GitHub repositories: thinkingbox and thinkingbox-data. This design isolates the runtime harness from domain scenarios, tool definitions, and datasets.
The core execution harness consists of several key components:
- The
tbCLI: A unified command-line interface supporting inference, metrics aggregation, side-by-side model evaluations, and terminal user interface (TUI) interactions. - MCP Session Proxy: A centralized HTTP service that manages isolated tool execution processes exposed through the Model Context Protocol (MCP). The proxy orchestrates server creation, lists tool schemas, dispatches tool execution requests, captures environmental side effects, and handles cleanup.
- Multi-Role LLM Loop: An execution loop that coordinates the agent model, an automated simulated user providing conversational context on demand, and an optional LLM-as-a-judge for subjective requirements.
The companion repository, thinkingbox-data, holds domain-specific packages, synthetic records, and scenario definitions. Real-world tools are implemented as MCP servers, keeping external dependencies isolated from the core runner.
Four Pillars of Stateful Agent Evaluation
ThinkingBox approaches task evaluation by establishing four controlled operational conditions:
- Known Initial State and Expected Outcome: Each task specifies a deterministic initial database state alongside expected end-state requirements, comparing changes against explicit records or database hashes.
- Controlled Tool Surface: The agent interacts exclusively through defined MCP tools. The framework maintains a clean separation between the agent’s observations and the underlying database records.
- Responsive Simulated User: Real-world tasks rarely supply all necessary parameters upfront. ThinkingBox utilizes an LLM user simulation that provides sensitive or omitted information—such as booking IDs or preferences—only when the agent prompts for it.
- Clean Isolated Environments: Each evaluation run executes in a freshly initialized environment managed by the MCP Session Proxy to prevent cross-test contamination or persistent side effects.
Testing Outcomes Instead of Trajectories
A key focus of ThinkingBox is assessing final outcomes rather than rigid tool sequences. Enforcing a strict step-by-step trajectory can penalize agents that resolve queries using valid alternate workflows, such as checking a support ticket before querying a user profile or recovering from transient read errors.
Instead of matching sequential tool call lists, ThinkingBox relies on post-execution assertions that query the final state of the environment. If the agent updates the database records correctly, the assertion passes regardless of the route taken. When non-database disclosures are required—such as stating that a booking request is subject to availability—the framework employs focused LLM-as-a-judge queries to verify conversational content.
ThinkingBox-Bench and Setup Requirements
Alongside the framework, Microsoft released ThinkingBox-Bench, a curated dataset containing 507 executable tasks across five business domains. Across initial benchmarks, Microsoft evaluated 12 proprietary and open-weight models using 20 trials per task to identify common failure modes in multi-turn tool interaction.
ThinkingBox is configured for Linux environments, including the Windows Subsystem for Linux (WSL). It requires Python 3.12 and is built for deployment with the uv package manager. The repository ships with an offline cloud_drive smoke-test scenario, allowing developers to verify their local tool proxies and API connections before running full benchmark suites.
Enjoyed this?
Get more posts like this delivered to your inbox.
NVIDIA Labs Introduces SoL-Pi for Coding Agent Efficiency
Next →Google Open-Sources ARTEMIS: An AI Android Automation Agent That Automates End-to-End Workflows, Captures Logs, and Connects to AI IDEs via MCP
Related Articles
Anthropic Adds Plugin Evaluation Framework to Claude Code
4 min read
OpenAI Introduces Agents API Powered by Codex Harness
4 min read